Kernel panic on fresh ZimaOS 1.7.0 install — ZimaBoard 2, reproducible, tied to ZimaNet/Open-iSCSI startup

So i got my Zimaboard2 a few weeks ago, last week started to fail on me, first once every day, then escalated and now wont survive 1 minute.

Full timeline of a ZimaBoard 2 crashing/instability issue that’s escalated to a reproducible kernel panic — posting the whole history since I think the progression matters, not just the final crash.

Setup: ZimaBoard 2, purchased ~2 weeks ago. ZimaOS v1.7.0. Kingston KC3000 NVMe. Apps: Pi-hole, Immich, Home Assistant, Uptime Kuma.

Day 1-2: Intermittent network disconnects
Board would suddenly vanish from the network — not pingable, not in router’s DHCP list, not SSH-able — while staying powered on. Recovered only via hard power cycle. Roughly every 1-2 days at first.

Root cause #1 — confirmed via coredumps: Found 8 separate segfault events across 3 days via coredumpctl, hitting different binaries (python3.11, python3.14, xtables-legacy-multi, dbus-broker). The clearest one: a SIGSEGV inside libpython3.14.so, triggered by crudini --get /etc/casaos/gateway.ini ssl port running under zimaos-welcome@tty1.service.

Mitigations applied: disabled EEE on the NIC, removed Tailscale (found it crash-looping), found ZimaNet (znet) was still running as a systemd service even after being toggled off in the Web UI — had to stop it manually via systemctl. Set up a hardware watchdog (iTCO_wdt) and a nightly reboot as safety nets.

Root cause #2 — audit backlog blocking new processes: Separately found auditctl -s showing backlog_limit 64 / backlog_wait_time 60000. When the audit queue filled, the kernel blocked new process creation (sshd sessions, websocket handlers) for up to 60s at a time, while ping/static content stayed responsive — looked like a full outage but wasn’t. Fixed live with auditctl -b 8192 --backlog_wait_time 0.

Root cause #3 — genuine ARP/link-layer drops: A separate, real issue: board stays fully healthy internally (confirmed via a custom health-monitoring script logging CPU/mem/temp every minute — all normal every time this happened) but vanishes from the router’s ARP table. Physical unplug/replug of the Ethernet cable fixes it instantly; a software-level ip link set eth0 down/up does NOT fix it. Never found the root cause of this one.

Persistence problems compounding everything: Discovered /var is tmpfs on this system — meaning cron jobs silently don’t survive any reboot. Had to move all scheduled tasks to systemd timers (/etc/systemd/system/*.timer) instead, since /etc is a persistent overlay. This wasted a lot of troubleshooting time since fixes kept silently reverting.

Escalation — corrupted overlay partition: Crash frequency accelerated to every 1-2 hours. Eventually a hard reset left the board unable to complete boot: journalctl -xb showed CasaOS overlay setup itself failing to start, and root/etc stuck read-only even after mount -o remount,rw (both / and the underlying /mnt/overlay ext4 partition). Nothing writable, including from rescue mode. This looked like corruption of the /etc overlay (upperdir on /dev/mmcblk0p7), likely from the accumulated hard power-cycles forced by all of the above.

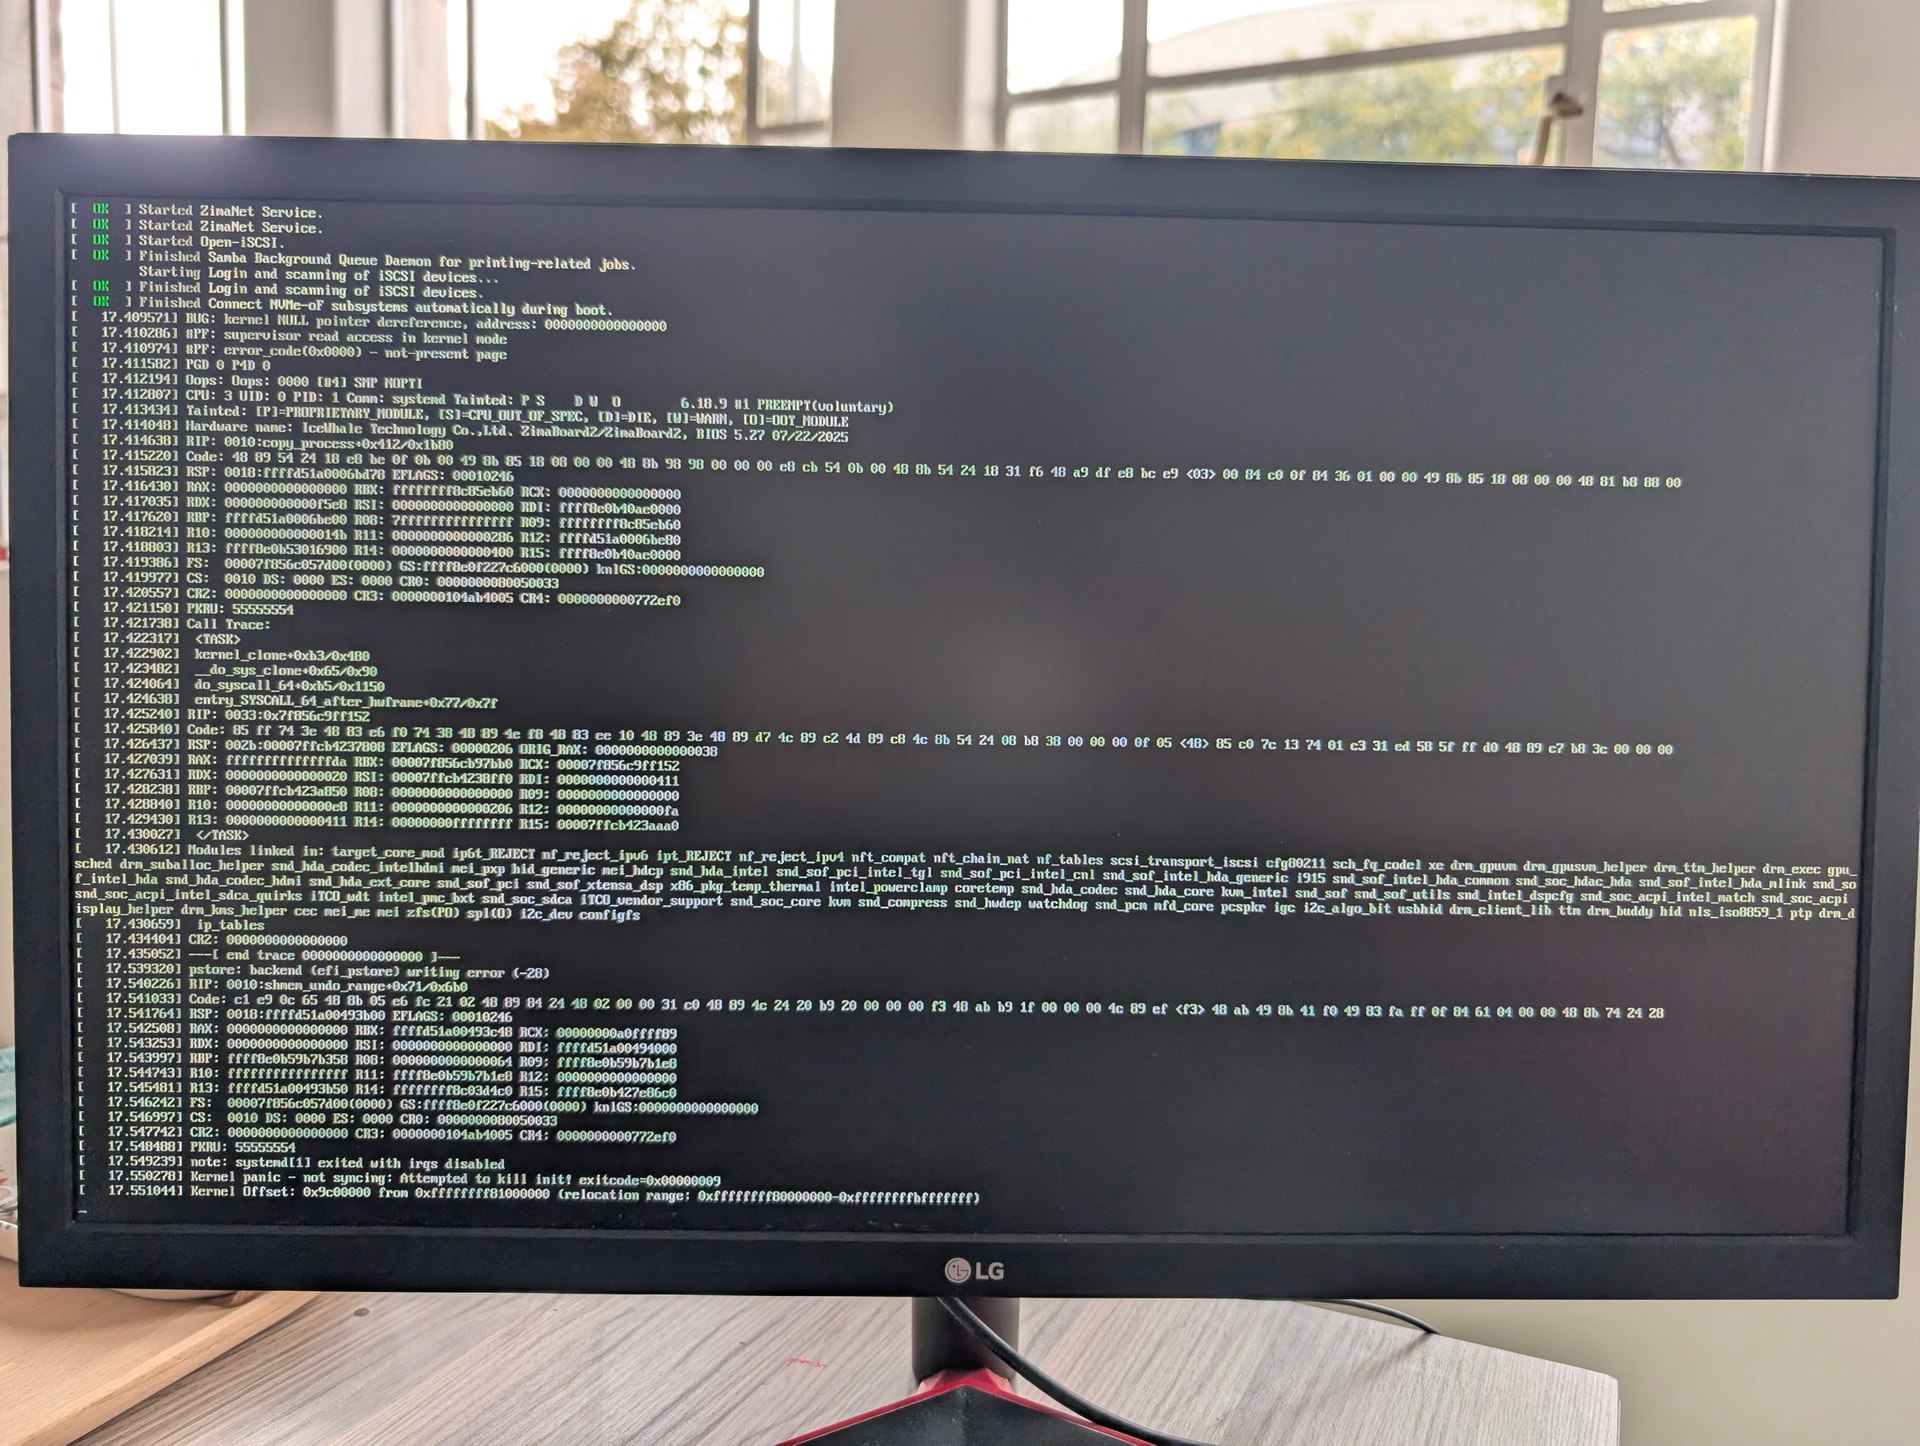
Full fresh reinstall: Reinstalled ZimaOS v1.7.0 from the official installer image onto the eMMC (NVMe left connected but untouched). On literally the first boot of the fresh, stock install — zero apps, zero config — it hit a full kernel panic:

This happened immediately after “Started ZimaNet Service” and “Started Open-iSCSI” in the boot log, while systemd was forking a new process.

Since then: repeated reboots have gotten progressively worse — from surviving ~7 minutes before freezing, down to freezing before the uptime counter even ticks past 0, sometimes not completing boot at all. Tested with the NVMe physically disconnected — crashes continued, so it doesn’t appear to be NVMe/storage related.

Where I’ve landed: this reproduces on a completely stock, freshly installed system with default config and no apps, so I don’t think this is anything user-side. I’ve emailed support directly with this timeline and the panic photo, and I’m stopping further hard reboots for now since each one seems to be making things worse, possibly further corrupting storage.

Given several people in the “ZimaOS crashing every 3 or so days” thread are seeing broadly similar unexplained lockups on different hardware, but this specific kernel panic (NULL pointer in copy_process, tied to ZimaNet/Open-iSCSI startup) is the first concrete kernel-level crash signature I’ve seen posted with a full trace — hoping it’s useful for narrowing this down, whether or not it turns out to be the same root cause as everyone else’s lockups. Prior discussion/logs from earlier in my troubleshooting: ZimaOS crashing every 3 or so days (posts #88-90).

Happy to share the actual photo of the panic screen if it helps, and to run any specific diagnostic before I do anything else with the board.
Update — found a clean, reproducible trigger.

After masking ZimaNet and the whole Open-iSCSI stack (znet, iscsid, iscsiuio, iscsi.service + their sockets), the board stayed fully stable over SSH — 19+ minutes idle, load average normal, no crashes. Best result all week.

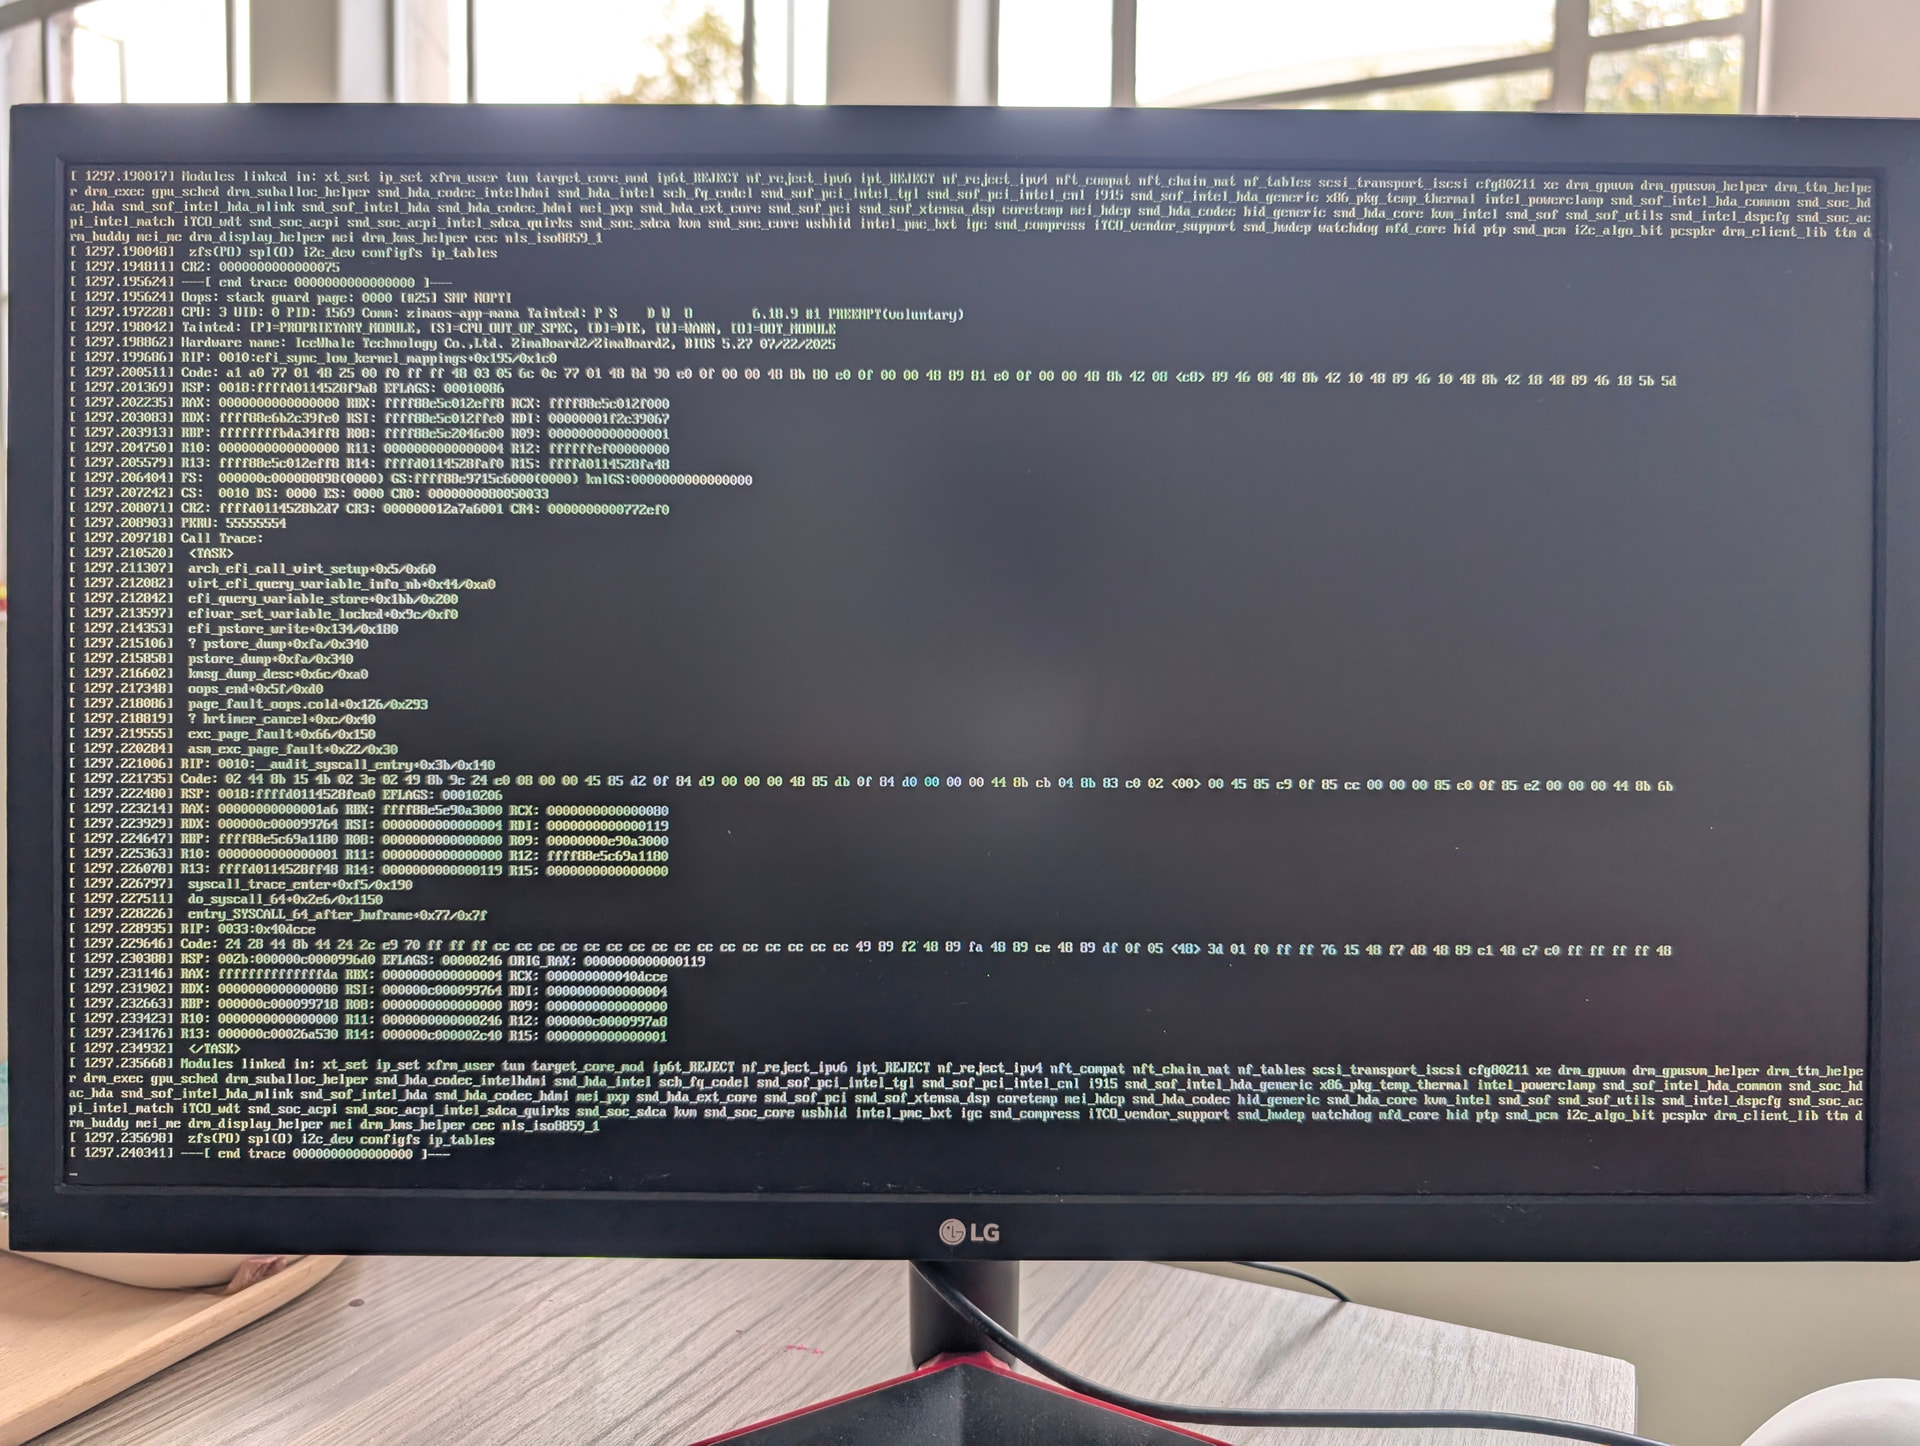
The moment I opened the Web UI dashboard, it crashed within 2-3 minutes. Full trace this time:

Oops: stack guard page: 0000 [#25] SMP NOPTI
CPU: 3 UID: 0 PID: 1569 Comm: zimaos-app-mana Tainted: P S D W O 6.18.9 #1 PREEMPT(voluntary)
RIP: 0010:efi_sync_low_kernel_mappings+0x195/0x1c0
Call Trace:
arch_efi_call_virt_setup+0x5/0x60
virt_efi_query_variable_info_nb+0x44/0xa0
efi_query_variable_store+0x1bb/0x200
efivar_set_variable_locked+0x9c/0xf0
efi_pstore_write+0x134/0x180
pstore_dump+0xfa/0x340
kmsg_dump_desc+0x6c/0xa0
oops_end+0x5f/0xd0
page_fault_oops.cold+0x126/0x293
...
---[ end trace 0000000000000000 ]---

So: zimaos-app-mana (App Management backend) hit a stack guard page fault (stack overflow) the instant the dashboard was opened, and then the kernel’s own crash-dump handler (trying to write the oops to EFI pstore) faulted a second time while handling the first fault.

This is now the third distinct process to trigger a kernel-level fault across my testing this week:

  1. crudini/Python 3.14 interpreter (SIGSEGV, earlier posts)
  2. systemd/copy_process (NULL pointer deref, fresh-install first boot)
  3. zimaos-app-mana (stack overflow, triggered by opening the Web UI)

Three unrelated userspace processes all independently causing kernel-level faults suggests this isn’t one buggy service — more likely something at the kernel build or EFI/firmware interaction level (the failed efi_pstore_write path in particular looks like a known-troublesome area on some UEFI implementations). Reproducibility now looks like: idle + no ZimaNet/iSCSI = stable; open the Web UI = crash within minutes.

Happy to test anything specific if it helps narrow this down further — at this point I can reproduce a crash on demand just by opening the dashboard.

1 Like

Thank you very much for your investigation and feedback. I will inform the developers, and they will follow up on your issue shortly.

1 Like

I will be the one to communicate with you regarding this issue, and I hope you can assist me in testing

1 Like

Thanks for getting in touch.
Investigating further into this, I ran some more tests: the official installer hung twice while writing to the eMMC (90%, 12+ min, required power cut both times), and the fresh reinstall crashed again on first boot with a kernel panic inside the memory allocator itself (kmem_cache_alloc/copy_process) — same call path as the original fresh-install panic. This now points toward a possible RAM/memory-controller hardware fault, not just a software regression.
After 3 boots hanged with no success, i mnnnaged it to start running, and it only lasted for about 9 minutes before it hung again.

I’ll be here in case we need more information, logs, or tests.

Thanks

Hey @piterdan I have some news, not good unfortunately. I got a mail from @Dina and was suggested that i downgrade to zimaos v 1.6.1 Did that and here are my findings since I think this settles an important question.

The downgrade does not fix the issue. The board still crashes on 1.6.1, but with a twist that I think is actually the most important finding yet: 1.6.1 runs kernel 6.12.25, versus 1.7.0’s kernel 6.18.9 — two completely different kernel builds — and it’s crashing on both.

Timeline from this test:

  • 1st boot attempt on 1.6.1: crashed shortly after boot
  • 2nd attempt: got stuck / hung
  • 3rd attempt: entered a self-triggered reboot loop, crashing and automatically rebooting roughly 5 times in a row
  • Captured multiple distinct crash signatures across these attempts:
  1. General protection fault in PID 1 (systemd), task_dump_owner, ending in “Kernel panic - not syncing: Attempted to kill init!” — same fatal pattern as the panics I reported on 1.7.0
  2. DMAR/IOMMU fault directly tied to eMMC storage I/O: “DMAR: ERROR: DMA PTE for vPFN already set”, crashing inside intel_iommu_map_pages, called from the eMMC block-request path (mmc_blk_mq_issue_rqcqhci_request)
  3. An RCU stall (CPU core detected as unresponsive by the scheduler, requiring an NMI-forced backtrace), followed by another DMAR fault and an i915 display FIFO underrun error

Given this now reproduces across two different OS versions and two different kernel builds, with faults specifically tied to the eMMC storage controller and IOMMU mapping (not any particular app, service, or driver I’ve disabled), I don’t think this can be a ZimaOS software regression. This looks like a hardware-level fault — possibly the eMMC controller, memory controller, or IOMMU hardware path.

Given the device is essentially unusable on both the current and previous OS release, and given everything documented so far (kernel panics, installer write failures to the eMMC, and now IOMMU/DMAR faults tied directly to storage I/O across two kernel versions), I’d like to formally request this be treated as a hardware fault for warranty purposes. I’ve also raised a claim with shop@icewhale.org but haven’t heard back yet — would appreciate if this could help move that along, or if you can point me to the right next step.

Happy to share the photos of all three crash traces if useful.

Thanks,
Rodrigo

Thanks for the detailed report, the photos, and the additional tests on ZimaOS 1.6.1.

The crashes across two kernel versions, faults in unrelated processes, installer hangs while writing to the eMMC, RCU stalls, and the DMAR fault in the mmc_blk_mq_issue_rq → cqhci_request path strongly suggest low-level board instability. Possible causes include the eMMC, the eMMC controller/DMA path, RAM or the memory controller, firmware, or power. The eMMC path is clearly involved in one trace, but that trace alone cannot distinguish the eMMC flash from the controller, IOMMU state, or corrupted DMA data in RAM.

First, please collect the system and boot information:

findmnt /

lsblk -o NAME,MODEL,SERIAL,SIZE,TYPE,FSTYPE,MOUNTPOINTS

It is normally /dev/mmcblk0.

please collect the identification and health fields exposed by the kernel:

{

for f in name manfid oemid serial date fwrev cid csd pre_eol_info life_time; do

if [ -r “/sys/class/block/mmcblk0/device/$f” ]; then

printf '%-16s ’ “$f:”

cat “/sys/class/block/mmcblk0/device/$f”

fi

done

} | tee ~/emmc-health.txt

The most important health fields are pre_eol_info and life_time.

For pre_eol_info:

0x01 = normal

0x02 = warning

0x03 = urgent

For each life_time value:

0x01 = approximately 0-10% of the rated lifetime used

0x02 = approximately 10-20%

0x0a = approximately 90-100%

0x0b = the rated lifetime has been exceeded

0x00 = not reported or not supported

These values mainly describe flash wear. Normal values do not rule out an intermittent eMMC controller, DMA, RAM, firmware, signal-integrity, or power fault.

Please also collect the system, firmware, and current kernel information:

uname -a

cat /proc/cmdline

sudo dmidecode -t bios -t system

cat /proc/sys/kernel/tainted

lsmod

Save the current kernel log:

sudo journalctl -k -b --no-pager -o short-monotonic \

| tee ~/kernel-current.txt

Collect the relevant hardware and kernel errors:

sudo journalctl -k -b --no-pager \

| grep -Ei ‘mmc|mmcblk|sdhci|cqhci|DMAR|IOMMU|I/O error|timeout|CRC|reset|Buffer I/O|EXT4-fs.*error|corrupt|MCE|EDAC|RCU|Oops|panic’ \

| tee ~/kernel-hardware-errors.txt

ZimaOS may also have saved previous crash records. Please run:

sudo find \

/sys/fs/pstore \

/var/lib/systemd/pstore \

/var/lib/casaos_data/.crash/pstore \

-type f -print 2>/dev/null

Please send us any files found in those locations.

Only if the board remains stable enough after collecting the information above, you can perform an optional read-only eMMC test.

First stop Docker and the container runtime:

sudo systemctl stop docker.service docker.socket containerd.service

sudo sync

In one terminal, monitor the kernel log:

sudo journalctl -kf

In another terminal, run:

sudo ionice -c3 nice -n19 \

dd if=/dev/mmcblk0 of=/dev/null bs=4M iflag=direct status=progress \

2>&1 | tee ~/emmc-read-test.txt

This dd command only reads the eMMC and does not write test data to it. Stop it immediately with Ctrl+C if new errors appear or the system becomes unstable.

Please do not run fsck on a mounted filesystem, and do not run badblocks -w or any other destructive write test.

Ok, thanks.

I’ll give it a try, but since the board won’t stay up more than a few minutes ill have to see how far I can go.

I’ll come back with the new findings.