Hi ZimaOS team,
I want to report a serious boot/storage issue that started after upgrading to ZimaOS v1.7.0. I am currently testing v1.7.1-beta1.
This issue has happened more than once, so it does not appear to be a one-time problem.
Environment:
- Device: ZimaCube
- ZimaOS: issue started on v1.7.0
- Currently running: v1.7.1-beta1
- System disk: NVMe
- casaos-data: /dev/nvme0n1p8, ext4
- Data HDD: 4 TB Btrfs (/dev/sda)
- HDD mount point: /media/HDD-Storage
- Docker data-root: /media/HDD-Storage/docker
- Applications affected: Nextcloud, Immich, MariaDB, SwingMusic, Hermes, etc.
Symptoms:
After reboot/startup, ZimaOS sometimes behaves almost like a fresh installation.
Observed symptoms include:
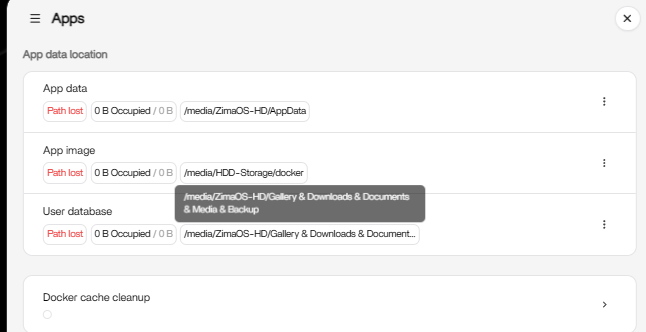
- HDD appears as “Path lost”
- /media/HDD-Storage is missing
- Docker fails to start
- Nextcloud and other applications become unavailable
- Existing applications/data appear to be missing from the UI
- ZimaOS may show setup/login behavior that looks like a fresh system
- /DATA, /media, /opt and /var/lib/casaos are not mounted correctly
- /media and /opt remain on the read-only SquashFS root filesystem
IMPORTANT:
The actual data is NOT deleted.
I manually mounted the 4 TB Btrfs HDD read-only and confirmed that all old data was still present, including:
AppData
Backup
docker
Documents
Downloads
Gallery
Media
The Docker data and containers were also intact.
Root cause found from logs
During boot:
10:06:30
systemd starts waiting for:
/dev/disk/by-label/casaos-data
Then:
10:06:44
systemd reports:
Timed out waiting for device /dev/disk/by-label/casaos-data.
Dependency failed for File System Check on /dev/disk/by-label/casaos-data.
Dependency failed for Grow File System on /var/lib/casaos_data.
Because var-lib-casaos_data.mount is unavailable at that moment, these mounts also fail with dependency errors:
DATA.mount
media.mount
opt.mount
var-lib-casaos.mount
zimaos-persistent-dirs.service
However, about 30 seconds later:
10:07:11
casaos-data finally becomes available and fsck starts.
Log:
casaos-data: recovering journal
10:07:13
casaos-data: clean
10:07:14
/dev/nvme0n1p8 is successfully mounted read/write on:
/var/lib/casaos_data
So casaos-data eventually mounts correctly, but the dependent bind mounts that already failed are NOT automatically retried.
This appears to be the main problem.
Effect on Local Storage
zimaos-local-storage-first.service starts before /media is correctly bind-mounted.
The log shows:
lstat /media/HDD-Storage: no such file or directory
trying to mount…
/dev/sda → /media/HDD-Storage
Then:
mkdir /media/HDD-Storage: read-only file system
auto import disk mount failed
At this point /media is still coming from the read-only SquashFS root filesystem instead of:
/var/lib/casaos_data/.media
Because of this, the HDD cannot be mounted and ZimaOS shows “Path lost”.
Effect on casaos-every-boot
casaos-every-boot.service also fails because the persistent bind mounts are missing.
Examples from the log:
ln: failed to create symbolic link ‘/media/ZimaOS-HD’: Read-only file system
cp: cannot create regular file ‘/DATA/.bash_profile’: Read-only file system
cp: cannot create regular file ‘/DATA/.bashrc’: Read-only file system
mkdir: cannot create directory ‘/opt/zimaos’: Read-only file system
This happens because:
/DATA
/media
/opt
are still pointing to the read-only SquashFS root instead of their persistent locations.
Manual recovery
I was able to fully recover the system WITHOUT formatting or reinstalling.
After /var/lib/casaos_data became available, I manually restarted the failed bind mounts:
var-lib-casaos.mount
DATA.mount
media.mount
opt.mount
zimaos-persistent-dirs.service
After that:
/DATA
→ /dev/nvme0n1p8
/media
→ /dev/nvme0n1p8[/.media]
/opt
→ /dev/nvme0n1p8[/.opt]
/var/lib/casaos
→ /dev/nvme0n1p8[/.casaos]
all became read/write again.
Then I restarted:
zimaos-local-storage-first.service
The 4 TB HDD immediately mounted correctly again:
/media/HDD-Storage
/dev/sda
btrfs
rw
All old files were visible again.
Docker
Docker is configured with:
{
“data-root”: “/media/HDD-Storage/docker”
}
After the HDD was restored, Docker started normally again.
Docker reported:
Docker Root Dir: /media/HDD-Storage/docker
Containers: 8
Images: 8
All previous containers were recovered and started successfully, including:
Nextcloud
Immich
MariaDB
SwingMusic
Hermes
This confirms that the application/data disappearance was caused by the failed mount sequence, not actual data deletion.
Additional v1.7.0 observations
After upgrading to v1.7.0 I also experienced abnormal CPU/RAM behavior.
At one point the system became extremely slow/unresponsive and restarted or became unavailable.
After recovery, icewhale-files was one of the highest CPU consumers:
/usr/bin/icewhale-files
~21% CPU
~300 MB RSS
I noticed that v1.7.1-beta1 includes:
“Fixed abnormal memory usage in certain file operation scenarios”
So this may be related, although I cannot confirm that the memory issue directly caused the mount problem.
I also observed zimaos-app-management panics:
runtime error: invalid memory address or nil pointer dereference
This occurred in HTTP request handling after boot.
Possible root cause
Based on the logs, this looks like a boot ordering/race condition:
casaos-data device appears too late
↓
var-lib-casaos_data.mount fails dependency
↓
DATA.mount / media.mount / opt.mount / var-lib-casaos.mount fail
↓
dependent services continue starting
↓
/DATA, /media and /opt remain on read-only SquashFS
↓
Local Storage cannot create /media/HDD-Storage
↓
HDD becomes “Path lost”
↓
Docker cannot access its data-root
↓
Apps such as Nextcloud appear missing/unavailable
About 30 seconds later casaos-data mounts successfully, but the failed dependent mounts/services are not automatically retried.
Expected behavior
If casaos-data is temporarily delayed during boot:
- ZimaOS should wait for it long enough, or
- dependent persistent mounts should automatically retry after casaos-data becomes available.
Services such as:
zimaos-local-storage-first
casaos-every-boot
Docker
app management
should not continue initialization while /DATA, /media, /opt and /var/lib/casaos are still unavailable/read-only.
Most importantly, the UI should not make the system look like a fresh installation just because persistent mounts temporarily failed.
I believe this is a high-risk issue because a normal user may see “Path lost” and a fresh-looking system and assume their data was deleted, possibly leading them to format/reinitialize a perfectly healthy disk.
Please let me know which additional logs or diagnostics would be useful. I can reproduce/check the system again if needed.
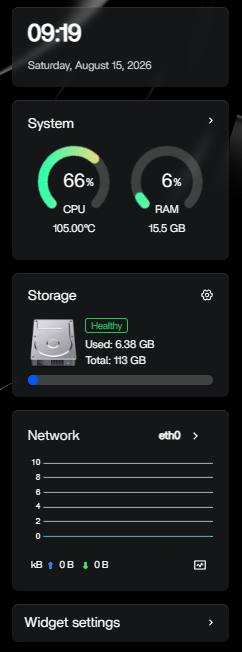
and CPU got really high normally isnt like this